Hydra is growing up. So we’re working on the boring parts.
Vacation season is finally over, which usually means entering that wonderful “back to school” period we all know and love…NOT!
However, even while on vacation – which was awesome, by the way – we somehow ended up with a myriad of new ideas and did enough brainstorming to occasionally fear that the proverbial fuse in our Slack workspace might actually blow.
Apparently, taking time off doesn’t necessarily mean your brain agrees to do the same.
Then again, sometimes you need to zoom out for a while to properly see where you are, what you’ve built and where you should go next. When you’re working on something every day, it is surprisingly easy to become focused on the next feature, the next support request or the next small improvement and lose sight of the bigger picture. Stepping away from the everyday routine gave us a chance to do exactly that.
So yes, rest is good sometimes. Especially when you’re doing it somewhere near the sea, with a beer in your hand.
And when we came back, we had quite a list.
Some of it is already visible.
The Hydra website has gone through a major overhaul. Support finally has a proper home and is not email based anymore (proper support tickets and all). Hydra Labs Insights now gives you a glimpse of what we’re currently working on. Last but certainly not least, one of the most requested features – Undo Check-in – has made its way into the app.
Built for real-world check-in.
See plans and choose what fits your workflow.
Some of it is considerably less exciting to look at.
Database queries. Data access. Synchronisation. How much information Hydra Bridge actually needs to fetch to answer a check-in request. How much of that information it really needs. What happens when thousands of attendees, multiple devices and a modest WordPress server all decide to become relevant at exactly the same moment.
You know. The fun stuff.
But that less visible work is becoming increasingly important as Hydra grows and gets used at more real events, under real conditions.
And real events are very good at finding assumptions. Especially when you take into account that we’re rapidly nearing the first 100k check-ins done with Hydra. Yes, you can congratulate us. Thanks.
First, we rebuilt Hydra’s home
The most obvious change is the website itself. But this was not simply a new coat of paint. Actually, it hasn’t changed much visually.
Hydra has changed considerably since the original website was built. Features were added, the documentation grew, different versions of the app appeared, Hydra.PULSE became part of the picture, and the number of questions that could reasonably be answered with a paragraph on a product page kept growing… And at some point, adding another link to another page stops being organisation.
So we gave the whole thing an overhaul.
The new website is intended to explain Hydra more clearly, make documentation easier to navigate and, perhaps most importantly, give support a proper home.
Until now, support worked but it was more fragmented than we wanted it to be. As the product grows, that becomes increasingly difficult for everyone involved. A question that has already been answered ten times should ideally become useful knowledge for the eleventh person rather than remain buried somewhere in an inbox.
The new support platform gives us a much better foundation for doing that.
It also gives us room to expand the documentation alongside the product instead of treating documentation as something that gets updated after the “real work” is finished.
Because documentation and support are part of the real work.
You can now peek into Hydra Labs
The overhaul also gave us somewhere to put something we had wanted for a while: Hydra Labs Insights.
Software roadmaps are awkward things.
Make them too vague and they tell you almost nothing. Make them too specific and suddenly an idea you were experimenting with three months ago looks like a contractual promise to ship something next Tuesday.
And development rarely works that neatly. So, Hydra Labs is our attempt to show more of the space in between.
It gives us a place to talk about things we are researching, testing, designing or actively building without pretending every experiment already has a release date attached to it.
Some ideas will make it into Hydra almost exactly as they first appeared. Others will change considerably once we start testing them against real workflows and some may turn out not to be good ideas after all.
That is fine.
The useful part is making the process a little more visible and giving some context to what we’re working on and, more importantly, why we’re working on it.
If you’ve ever wondered what is currently occupying our Slack workspace and threatening that aforementioned proverbial fuse, Hydra Labs is probably where you’ll find the answer.
And you can join too! On that same page, you can send us your ideas (no matter how crazy… we’re used to those). So, take this as an open invitation for collaboration.
Undo Check-in finally happened
Speaking of things people have asked for: Undo Check-in is now part of Hydra. And yes, “finally” is probably justified here.
Undo has been one of the most frequently requested features, and at first glance it sounds almost embarrassingly simple. Someone was checked in by mistake. Press a button. Undo it. Done.
Except check-ins don’t exist only as a number on one screen.
Hydra can have multiple devices working on the same event. Those devices can move between online and offline states. They can synchronise over Hydra.PULSE. Operations can be queued. Different users can have different permissions. And whatever happened at the door still needs to make sense when someone looks at the history later.
Simply subtracting one from a counter would have been easy. It also would have been wrong.
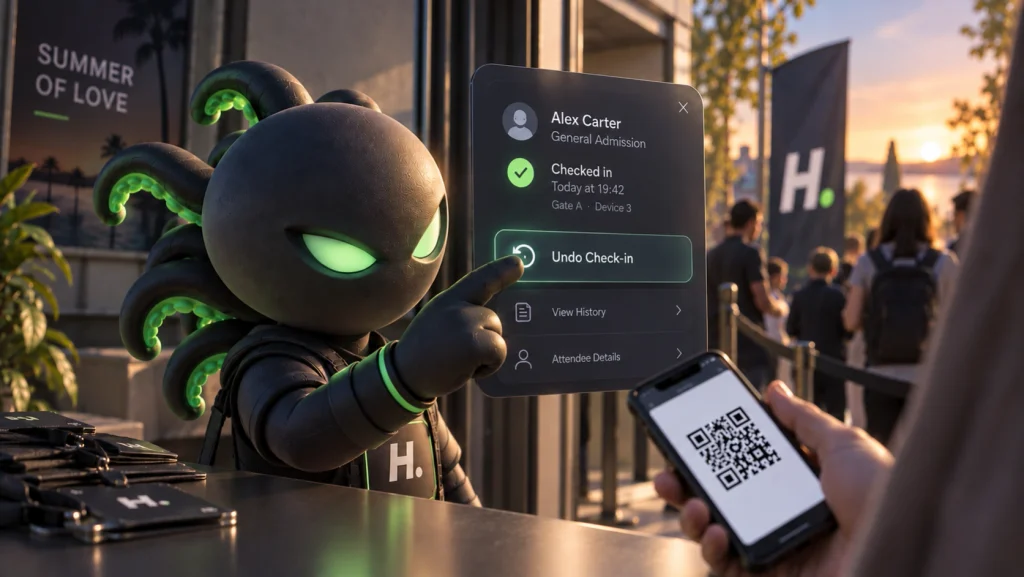
So Undo was implemented as a proper operation with permissions, synchronisation behaviour and history behind it. An authorised operator can reverse a check-in from Attendee Details, while Hydra keeps enough context to know that a check-in existed and was deliberately reversed.
That may sound like considerably more engineering than an Undo button deserves. It probably is.
But doors are chaotic places. Someone scans the wrong ticket. A guest hands over two tickets and the wrong one gets selected. An operator taps something twice. You know… just humans continuing being humans.
The software should be able to deal with that without rewriting history.
A real event gave us our next homework assignment
Recently, one Hydra installation gave us a particularly useful real-world stress test. It involved a large attendee dataset, a substantial number of check-ins in a relatively short period of time and a WordPress server already operating fairly close to the limits of its available resources.
That combination exposed inefficiencies that are much harder to notice on a development machine or a lightly loaded website.
The immediate issue was investigated and addressed before the event started, including several targeted fixes along the way.
The more interesting question came afterwards: Why stop there?
A hotfix can solve the problem in front of you but it doesn’t necessarily solve the reason that problem was possible in the first place. Looking more closely at what happened showed us that some of the data access performed by Hydra Bridge was simply doing more work than Hydra actually needed.
That turned one support situation into a much broader performance audit and, ultimately, into a change of priorities.
Hydra doesn’t need to know everything
WordPress installations can contain an enormous amount of information.
Add an e-commerce system, a ticketing solution, attendee metadata, orders, events, custom fields and years of accumulated data, and there can be quite a lot happening underneath what appears to the person at the entrance as a very simple operation: Scan ticket. Valid or not?
Hydra only needs a relatively small subset of all that information to answer that question and perform a check-in correctly. The path to obtaining that information, however, can become much more complicated.
So the first stage of the current optimisation work is all about re-auditing how Hydra Bridge accesses data in the first place.
- Which queries are being made? How much data do they retrieve?
- How often are we asking WordPress or the underlying ticketing system for information that hasn’t changed?
- Can the data Hydra needs most frequently be prepared or consolidated more efficiently?
- Can we reduce both the database work on the server and the amount of information that has to travel between Hydra Bridge and the app?
Those are all the questions that are becoming more and more interesting the deeper we dig in.
The goal is straightforward: Hydra should ask for the smallest amount of information necessary to do its job, and the server should have to do the smallest reasonable amount of work to provide it. This is particularly important for large attendee datasets and installations running on modest infrastructure when throwing more CPU and RAM is not always an option.
Fast check-in shouldn’t require an expensive server
Event infrastructure varies wildly. Some organisers run their websites on powerful dedicated infrastructure. Others run perfectly respectable WordPress installations on relatively modest hosting because, for the other 364 days of the year, that is all they need.
Then the doors open.
Suddenly a website that normally serves pages to visitors is also being asked to participate in a burst of operational activity where multiple devices may be checking people in at the same time. That is a very different workload.
Our aim is not to pretend server resources don’t matter. They obviously do. The aim is to make sure Hydra isn’t wasting the resources that are available. A smaller server doing necessary work is one thing but a smaller server doing unnecessary work is something we can improve. And that is what we’re working on.
Hydra.PULSE is still there when the server shouldn’t be
Of course, there is another way to reduce the server’s involvement in check-in: simply don’t involve it.
Hydra was designed around offline check-in from the beginning, and Hydra.PULSE extends that idea to multiple devices working together over a local network.
For high-volume events, unreliable internet connections, venues with questionable connectivity or situations where repeatedly reaching the remote WordPress server simply doesn’t make sense, that remains an important option.
Devices can work with attendee data locally and coordinate over the local network instead of making every scan depend on a round trip across the internet.
The current Hydra Bridge optimisation won’t be replacing that approach but will rather complement it.
There are events where normal online check-in is perfectly appropriate, and we want that path to be as efficient as possible. But there are also events where removing the internet and remote server from the critical check-in path is simply the better architecture.
And Hydra should be comfortable doing both.
And somewhere behind all of this is Hydra Stats
There is also another project waiting in the wings. Hydra Stats.
The idea behind Hydra Stats is to go considerably further than the basic numbers currently available and provide a proper reporting layer for Hydra check-ins. We’re talking about a more granular view of check-in activity, useful event-level reporting, check-in history that can be explored rather than merely counted, and exportable reports for the things organisers need to do after the last guest has walked through the door.
There are plenty of interesting directions this can go. But there is a dependency. Stats will need to ask questions of the same underlying data that Hydra already uses operationally. Potentially quite a lot of questions. So, building an increasingly sophisticated reporting layer before optimising how that data is accessed would be doing things backwards. We would effectively be adding more queries on top of a data path we’ve already identified as something worth improving.
So Hydra Stats is coming. But first, we’re doing the plumbing which is considerably less glamorous. But it is also the right order.
Features are only half the job
It is tempting to measure software development by things you can point at. Here’s a new screen, a new button, a new report… Those things are satisfying because the difference between yesterday and today is immediately visible. But software that is actually being used also needs another kind of development. Sometimes the most useful thing we can build is a feature people have been requesting for months but sometimes it is just a better support system.
And sometimes it is spending several days investigating database queries so that a person scanning ticket number 4,387 at a busy entrance never has to know those queries existed.
Apparently vacation season really is over.